Tag: Google

  • Google’s Digital Journalism Programme Trains Over 4,000 Pakistani Journalists in AI Tools

    Google’s Digital Journalism Programme Trains Over 4,000 Pakistani Journalists in AI Tools

    Google’s Digital Journalism programme has trained more than 4,000 Pakistani journalists, media professionals and students in the use of artificial intelligence (AI) tools since its launch in September 2024, ARY News reported on Tuesday.

    The training has been delivered through more than 60 master trainers across Punjab, Sindh, Khyber Pakhtunkhwa and Balochistan, with the programme run in partnership with Tech Valley and leading educational institutions and government departments.

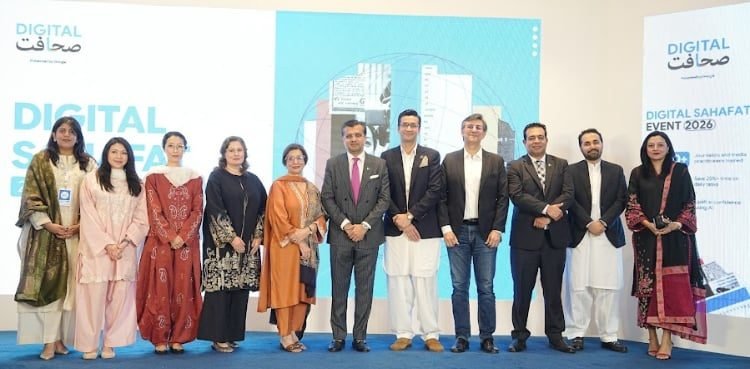
    The figures were shared at the Digital Sahafat Event 2026 held at a hotel in Lahore, attended by Ali Dar, adviser to the Punjab chief minister on artificial intelligence, international cooperation and special initiatives; Hum Network chairperson Sultana Siddiqui; and Google’s managing director for news partnerships, Kate Beddoe, along with policymakers and senior journalists.

    Addressing the event, Ali Dar said the government could not do this work alone and that Google, Tech Valley, universities and media organisations needed to work together.

    The programme aims to equip Pakistani journalists with modern AI tools for verifying information, working faster and building sustainable newsroom practices, the event heard.

    A survey of participants found that 85 percent had made Google’s AI tools a permanent part of their daily work, while around 68 percent said they were saving more than 25 percent of their time on daily research and reporting. Participants also reported a 260 percent increase in their professional confidence in using AI tools, according to the survey. Google said it has trained more than 2.5 million journalists in 120 countries worldwide.

  • Google’s Gemini Omni 1.2 Flash Makes 15-Second AI Videos — and Cuts the Price 30%

    Google’s Gemini Omni 1.2 Flash Makes 15-Second AI Videos — and Cuts the Price 30%

    Google has made its newest AI video model, Gemini Omni 1.2 Flash, generally available — and the headline upgrade is simple: clips can now run for 15 seconds instead of 10, while costing 30 percent less than the model it replaces.

    The model was announced on 5 November by Google DeepMind and is available through the Gemini API and Gemini for business on Google Cloud. It creates and edits video with native sound, and users can pick any whole-second length from 3 to 15 seconds, giving creators room to tell a complete story, make a product explainer or build a full social-media advert in a single generation.

    Price is the other big change. Google has cut the cost to $0.07 per second for 720p video, down 30 percent from Omni 1.1. Creators can draft quickly at lower resolutions, fix details with a follow-up edit instead of starting again, and then upscale their best work to 1080p or 4K.

    Editing in conversation, not from scratch

    Omni 1.2 Flash also brings multi-turn conversational editing. Instead of regenerating a whole clip, users can refine the same one turn by turn — swapping a background, changing the lighting or weather, or switching the aspect ratio — while the characters, framing and action stay in place.

    Google says the model follows references far more closely than before. It can work from character, product or style images, short motion clips of up to three seconds and audio cues, keeping faces, clothing, packaging and brand colours consistent across camera angles and cuts. That makes it suited to virtual try-on clips, catalogue spins and branded video adverts built from existing product photography.

    Speech is another focus. The model produces more fluid, natural-sounding dialogue with clearer lip-sync and distinct voices for different characters in the same scene, and it can direct sweeping camera moves — from first-person flythroughs to dramatic zoom-outs — with fewer unwanted jump cuts, according to Google.

    The model is rolling out across Google’s products. Developers can use it in Google AI Studio and the Gemini API, businesses through the Google Cloud console, and consumers in Flow, Google Vids — where 15-second clips are available at no additional cost — the Gemini app for Google AI Ultra subscribers, and Google Ads. Outputs carry an imperceptible SynthID watermark so AI-generated video can be identified.

    Google says work is still under way on fast sports action, rapid script changes and complex physics, but for businesses, developers and creators producing video at scale, the longer clips and lower price make Omni 1.2 Flash the company’s main video model going forward. From 3 December, requests sent to the older 1.1 model will automatically be routed to 1.2.

  • AI Training Opt-Out: One Shared Robots.txt Rule

    AI Training Opt-Out: One Shared Robots.txt Rule

    Google, Microsoft and OpenAI have announced plans to honour a single shared robots.txt line that lets a website state its AI training preference once, instead of writing separate rules for each company’s web crawler. The move, reported on 1 November, could simplify life for publishers who want to keep their content out of generative AI training.

    At present, a site that wants to refuse AI training must write different rules for different crawlers, such as Google-Extended, GPTBot and others. Under the new approach, a site would write one ordinary rule group under a policy token called __usage_ai-training, using the familiar Allow and Disallow lines. An example in the proposal blocks an entire site except for its press-kit folder.

    The line comes from an Internet Draft submitted on 30 October by Kevin Kelley of Anthropic to the AI Preferences working group at the Internet Engineering Task Force (IETF). The draft is listed as an individual submission, which means it does not represent official IETF standardisation activity, and it is set to expire on 3 May 2027 unless a new version is published.

    How the shared signal works

    The draft adds no new directive to robots.txt. It reuses the file’s existing structure, but instead of naming a crawler on the User-Agent line, it names the policy token. The draft defines AI training as using content to modify a generative model’s learned parameters, and it says models that only do non-generative work, such as classification or ranking, are exempt.

    There are important limits. A wildcard group, written as User-Agent with an asterisk, can never match the token, and a robots.txt file with no __usage_ai-training group signals no preference at all. The token is also a statement about how content may be used, not an instruction about crawling itself, so it does not stop a crawler from visiting a site.

    Different timelines for each company

    Based on the timelines the companies gave, none of the three currently supports the shared line yet. Google aims to support it in early 2027, and says that where a site opts out through the shared line without specifying Google-Extended, it will treat that as if the publisher had disallowed Google-Extended, a control covering future Gemini model training and grounding in Gemini Apps and on Vertex AI.

    Microsoft will begin honouring the new options as it crawls from 1 February 2027, and will stop recognising its NoArchive and NoCache tags as training or grounding signals after 1 March 2027. It is also adding a separate page-level AI Grounding preference, which can be set by a meta tag or an HTTP header, with a DisallowExtended option that limits grounding to Microsoft’s own tools.

    OpenAI aims to honour the signal within the next few months, while its current robots.txt policy stays in effect. Anthropic, whose engineer wrote the proposal, has said it has already started building support. Microsoft has also warned that blocking AI grounding will significantly reduce a site’s visibility in AI-generated experiences, and that the new preferences do not establish licensing or payment arrangements.

    For publishers, the appeal is simplicity: one line, recognised by several companies, instead of a patchwork of crawler-specific rules. The open question is how consistently the companies will interpret that line once support actually arrives.
  • Google Astra Chip: 40% Less Power for Edge AI Wearables

    Google Astra Chip: 40% Less Power for Edge AI Wearables

    Google Research has previewed a new line of low-power artificial intelligence chips designed to bring smarter AI directly onto wearable devices, promising to cut energy consumption by 40 per cent compared with existing products. The Astra chip line, developed jointly with American chipmaker Synaptics, was unveiled on Wednesday at Google’s annual Research@ showcase at the company’s headquarters in Mountain View, California.

    Unlike conventional AI chips that send data to distant cloud servers for processing, the Astra chips are built for edge AI — running artificial intelligence tasks directly on small devices such as smart glasses and smartwatches. Because the processing happens on the device itself, responses are faster and the risk of sensitive data leaking during transmission is reduced. The trade-off has always been that such chips must be extremely power-efficient and produce little heat, a barrier Google says its new hardware now overcomes.

    Always-on AI ambition

    Avinatan Hassidim, vice president of Google Research, said conventional edge chips were slow and used too much energy, making an always-on ambient AI experience impossible. The new chip uses the M2, a successor to the Coral Neural Processing Unit, an AI compute engine Google introduced last year. The chip is expected to handle voice, video, motion and context detection in real time on wearable devices, allowing phones and glasses to understand their surroundings continuously without constantly waking power-hungry main processors.

    Rahul Patel, the chief executive of Synaptics, said the chip would not stay in the laboratory and would be built into Google devices, although he did not specify which products or when they would be released. Synaptics plans to reveal detailed specifications and demonstrate the chip at its own event on October 20. The partnership extends the two companies’ earlier collaboration: Synaptics unveiled the first Astra chip series last October, the first to commercialise Google’s Coral neural processing platform, and earlier this year built the Coral Board development platform around it.

    At the same event, Google Research also shared other projects, including Google Earth AI for predicting environmental and public health conditions, Deep Review for checking the logic and factual accuracy of technical documents, and TimesFM, a forecasting model for time-series data. The Astra announcement reflects a broader industry shift toward on-device intelligence, as companies race to put AI assistants into wearables that users can wear all day without draining the battery.